RAG · LangChain
YouTube Transcript Q&A
Ask questions about any YouTube video and get answers grounded in what was actually said, instead of the model's guesses.
The problem
Long videos such as lectures, talks and tutorials hide the one answer you need somewhere in an hour of speech. Asking a general chatbot about them is risky: it hasn't watched the video, so it may invent an answer.
This project lets you ask questions about a specific video and answers only from its transcript.
How it works
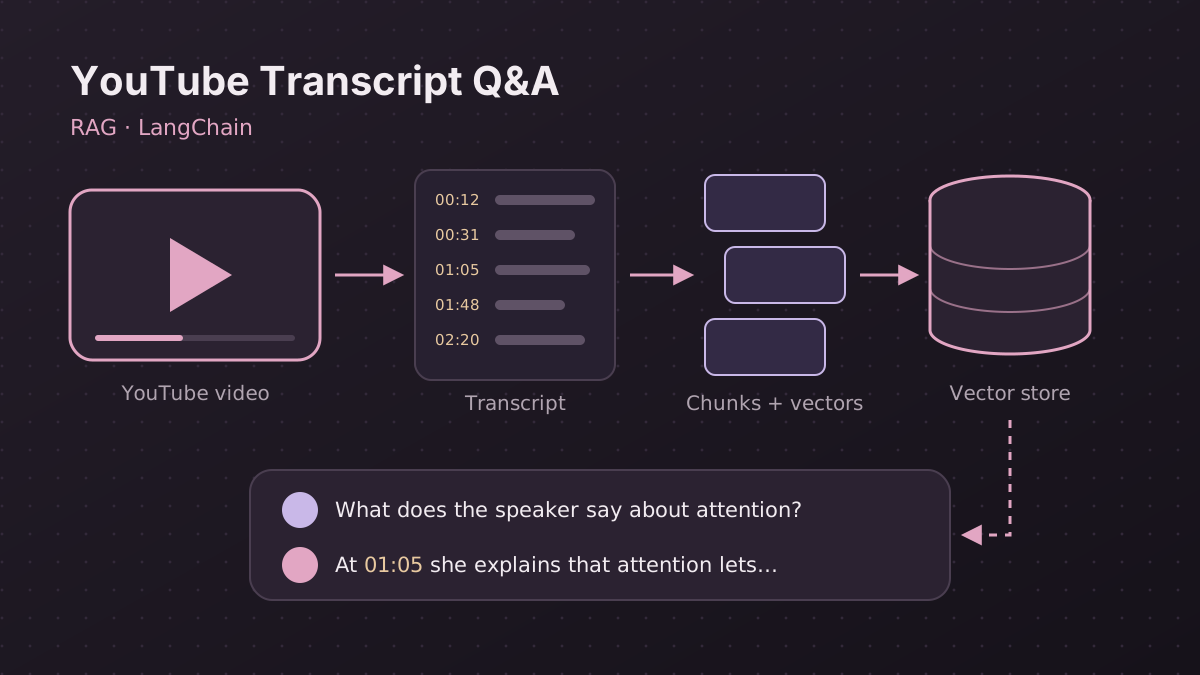
Load the transcript
Takes a YouTube video and retrieves its transcript, the text of everything said in the video.
Split into chunks
Splits the transcript into overlapping pieces with LangChain text splitters, so each piece is small enough to search but keeps its context.
Embed and store
Turns each chunk into an embedding (a vector of numbers that captures its meaning) and stores them in a vector store.
Retrieve and answer
For each question, finds the most relevant chunks and gives them to an LLM, which writes an answer based only on those passages.
What I learned
Building a full RAG pipeline end to end with LangChain: loading documents, chunking strategy, embeddings, retrieval, and prompting an LLM to stay grounded in the retrieved context.